Credit Scoring Analysis and Modeling
This project develops a credit scoring model that predicts loan repayment likelihood for people without traditional banking histories. It uses alternative data sources such as mobile usage and transactional data to assess creditworthiness.
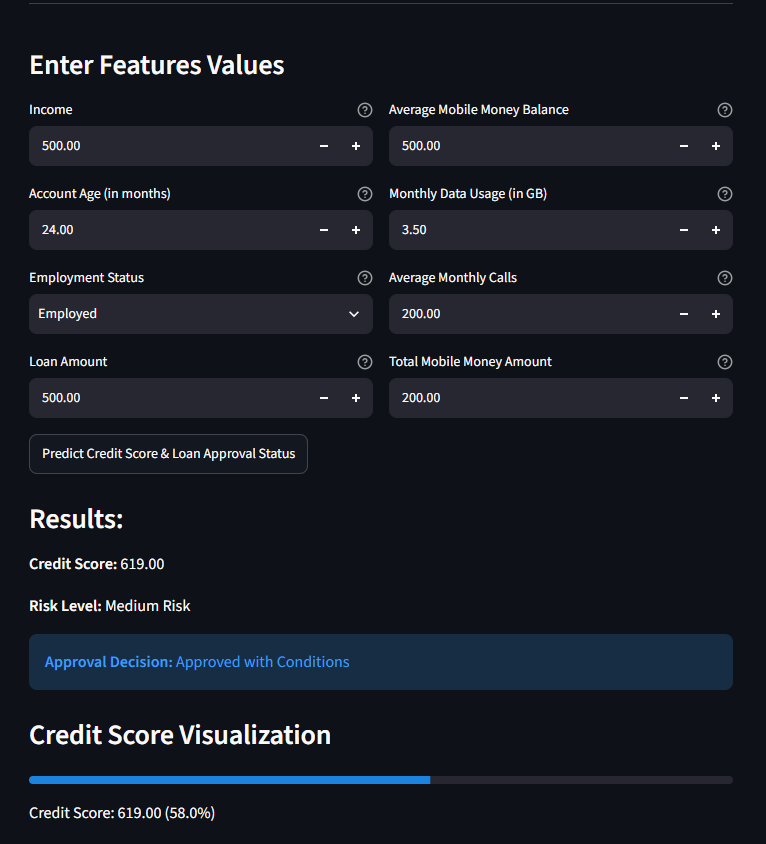
Project overview
This project aims to develop a credit scoring model that can predict loan repayment likelihood for people without traditional banking histories. The model utilizes alternative data sources such as mobile usage and transactional data to assess creditworthiness.
Access to credit is a critical component of financial inclusion, but traditional credit scoring methods often exclude underbanked populations. By leveraging alternative data sources, this project explores new approaches to assess credit risk and expand financial access.
The analysis integrates data from the following tables in a local MySQL database:
customers: Demographic information for loan applicantscreditscorehistory: Historical credit score dataloanapplications: Loan application details and statusmobileusage: Mobile usage metrics, including data usage and call timetransactions: Customer transaction history
Key findings
- Demography: Average income, age, and account age vary significantly by country, while employment status distributions show higher rates of self-employment and informal work in some countries.
- Transactions: Customers show diverse monthly spending patterns, ranging from consistent spending to high volatility.
- Loan applications: Approval rates are higher for salaried employees than for self-employed or informally employed applicants, helping identify high-risk profiles.
- Credit scores: Average credit score trends downward over time, potentially indicating deteriorating creditworthiness and providing an early warning signal for lenders.
- Mobile usage: Data usage and call time correlate with income and may provide useful predictive features for credit assessment.
Approach & tools
The model was developed using a Random Forest Classifier and achieved 60% accuracy on the test set. Features were engineered from income, account age, employment status, and loan amount.
Hyperparameter tuning was performed with GridSearchCV to optimize model performance. The analysis used Python, machine learning, SQL, and a local MySQL database for data preparation and exploration.
Project impact
This project demonstrates the potential of alternative data sources and advanced analytics to develop credit scoring models that better serve underbanked and underserved communities. The resulting insights can contribute to improving financial inclusion and access to credit for people traditionally excluded from the formal financial system.
Future improvements include enriching the feature set with mobile money transactions, social media activity, and utility bill payments; testing XGBoost or LightGBM; adding SHAP or LIME explainability; and deploying the model through a production-ready application or API for real-time credit assessment.
Explore the work
Open the project repository to review the analysis, notebooks, SQL, dashboards, or supporting files.
Start a conversation
Have a data question or project in mind?
Let’s talk about the problem you’re trying to solve and how data can help.